Technical AnalysisEngineering
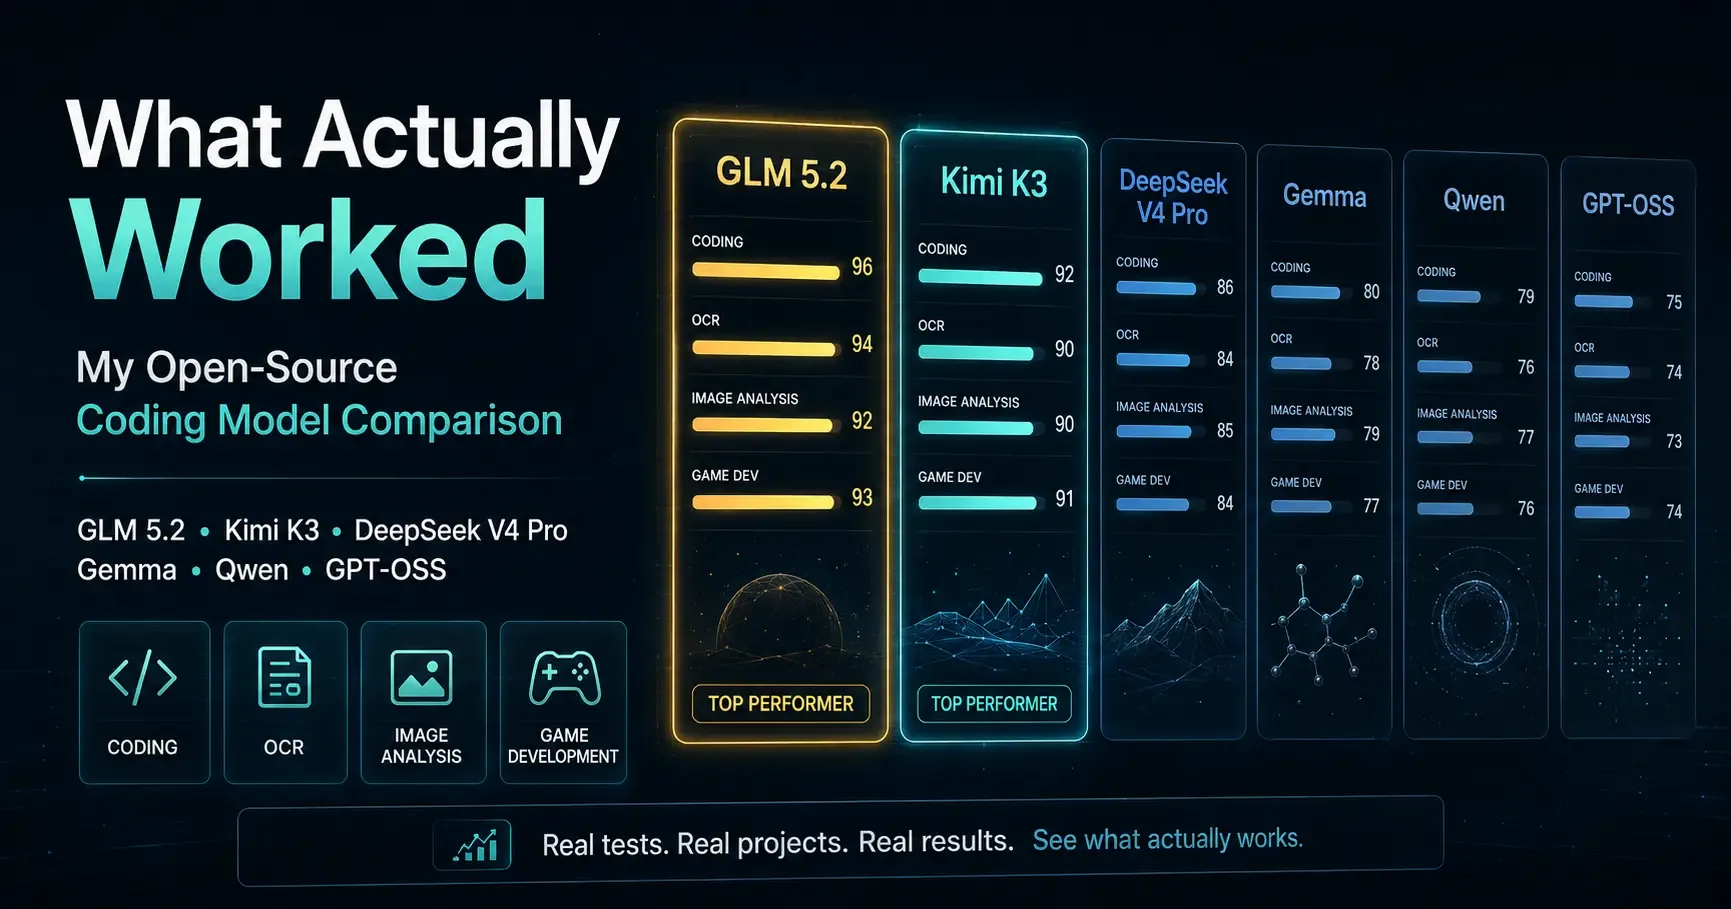
What Actually Worked: My Open-Source Coding Model Comparison
A hands-on comparison of six open models across coding, OCR, image analysis and game development, measured by usable output rather than benchmark claims.
Gitforce Insights
Practical perspectives from the Gitforce team on software testing, engineering, and enterprise AI.
Featured insights
A hands-on comparison of six open models across coding, OCR, image analysis and game development, measured by usable output rather than benchmark claims.
Latest articles
3 published articles
A hands-on comparison of six open models across coding, OCR, image analysis and game development, measured by usable output rather than benchmark claims.
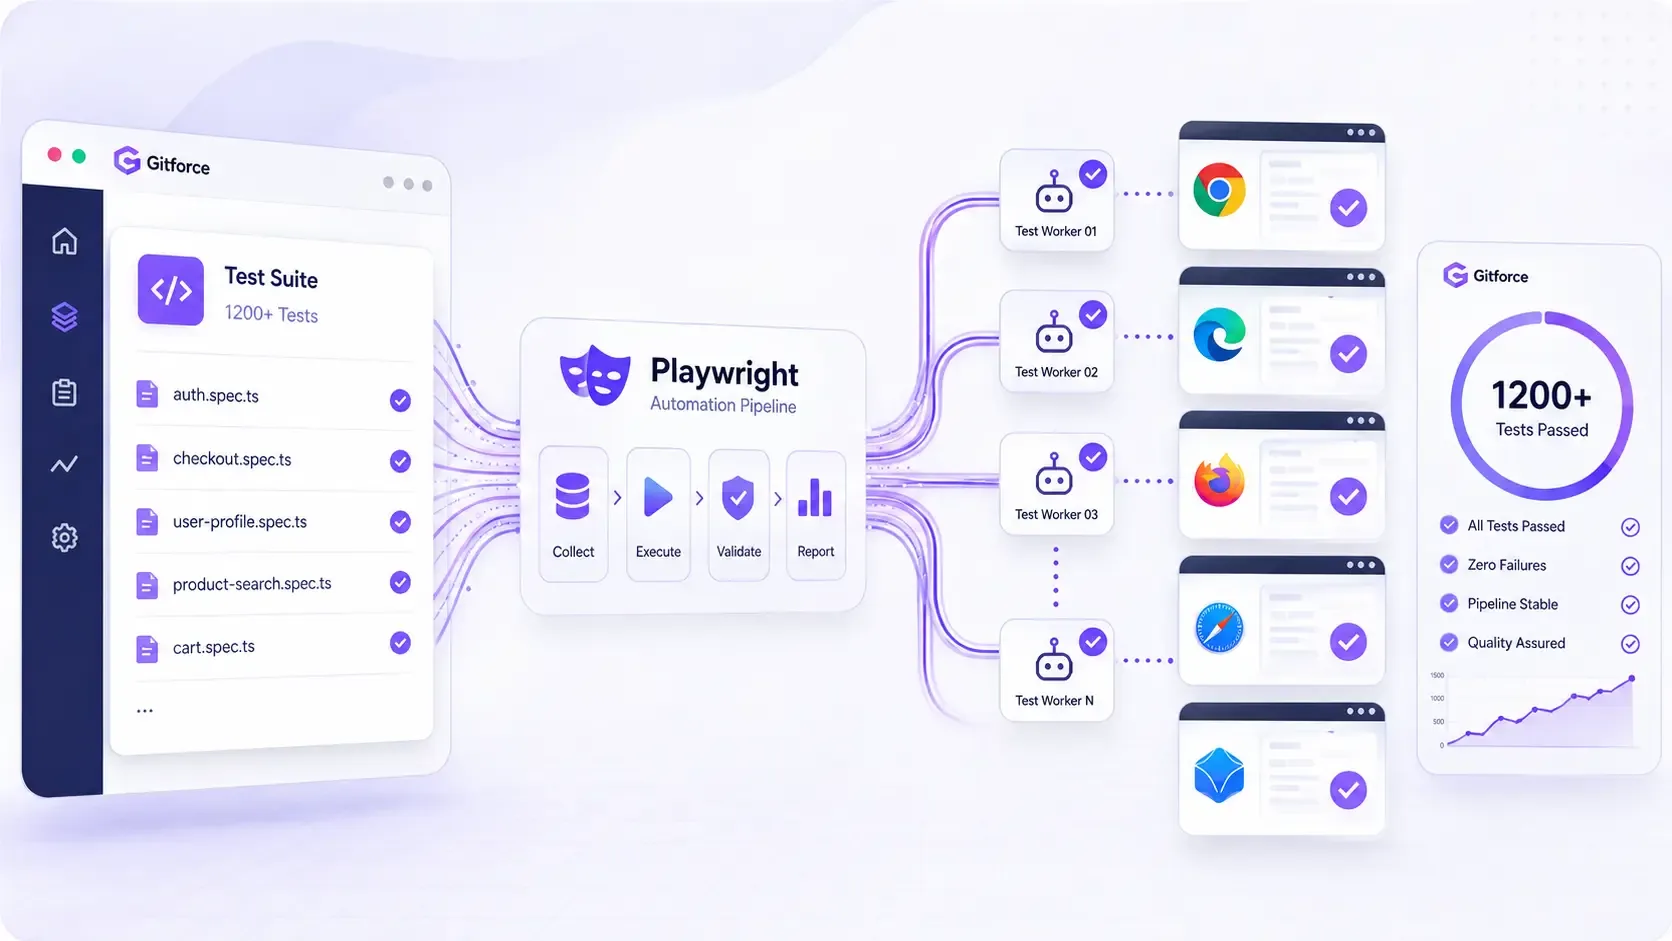
How a deterministic Playwright framework, manifest-driven test design, controlled state, and single-worker execution reduced a 623-test suite from eight hours to about 1.5 hours.
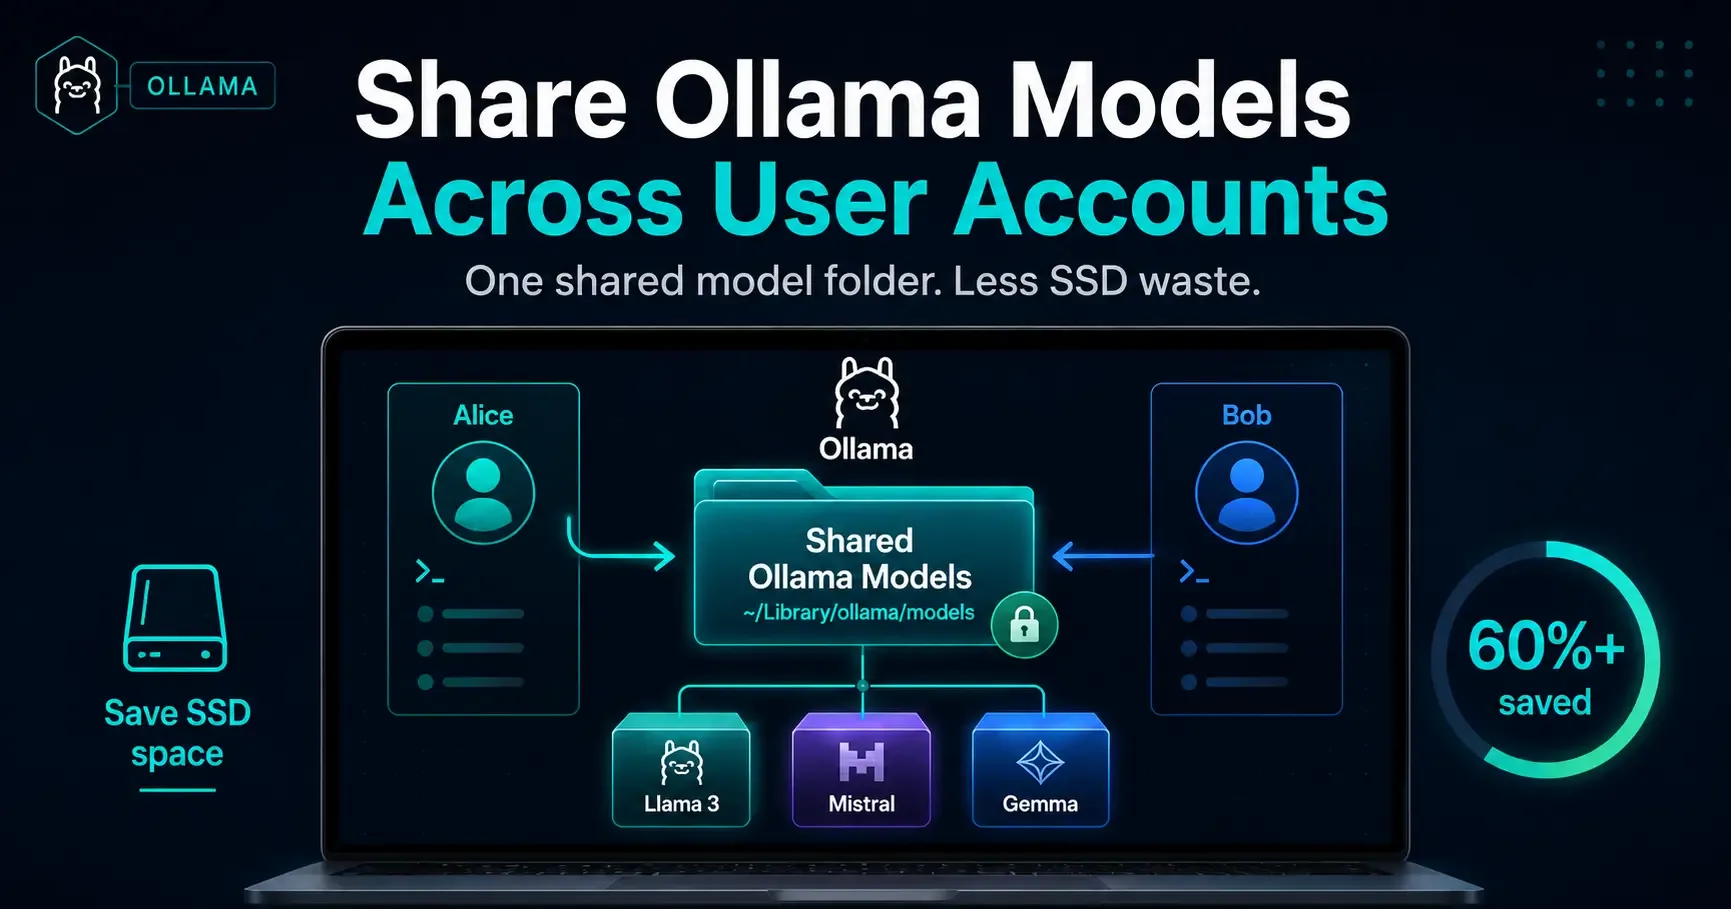
A practical guide to choosing, running, and sharing Ollama models across macOS, Linux, and Windows without wasting disk space.